Publications  /  Rigged Backtest

Can LLMs Catch a Rigged Backtest? A Clean-Control Calibration Benchmark
M. Ulesov, V. Smirnov, O. Ibrahim, A. Bobovnikov

Accepted EMNLP 2026 · FinNLP Workshop

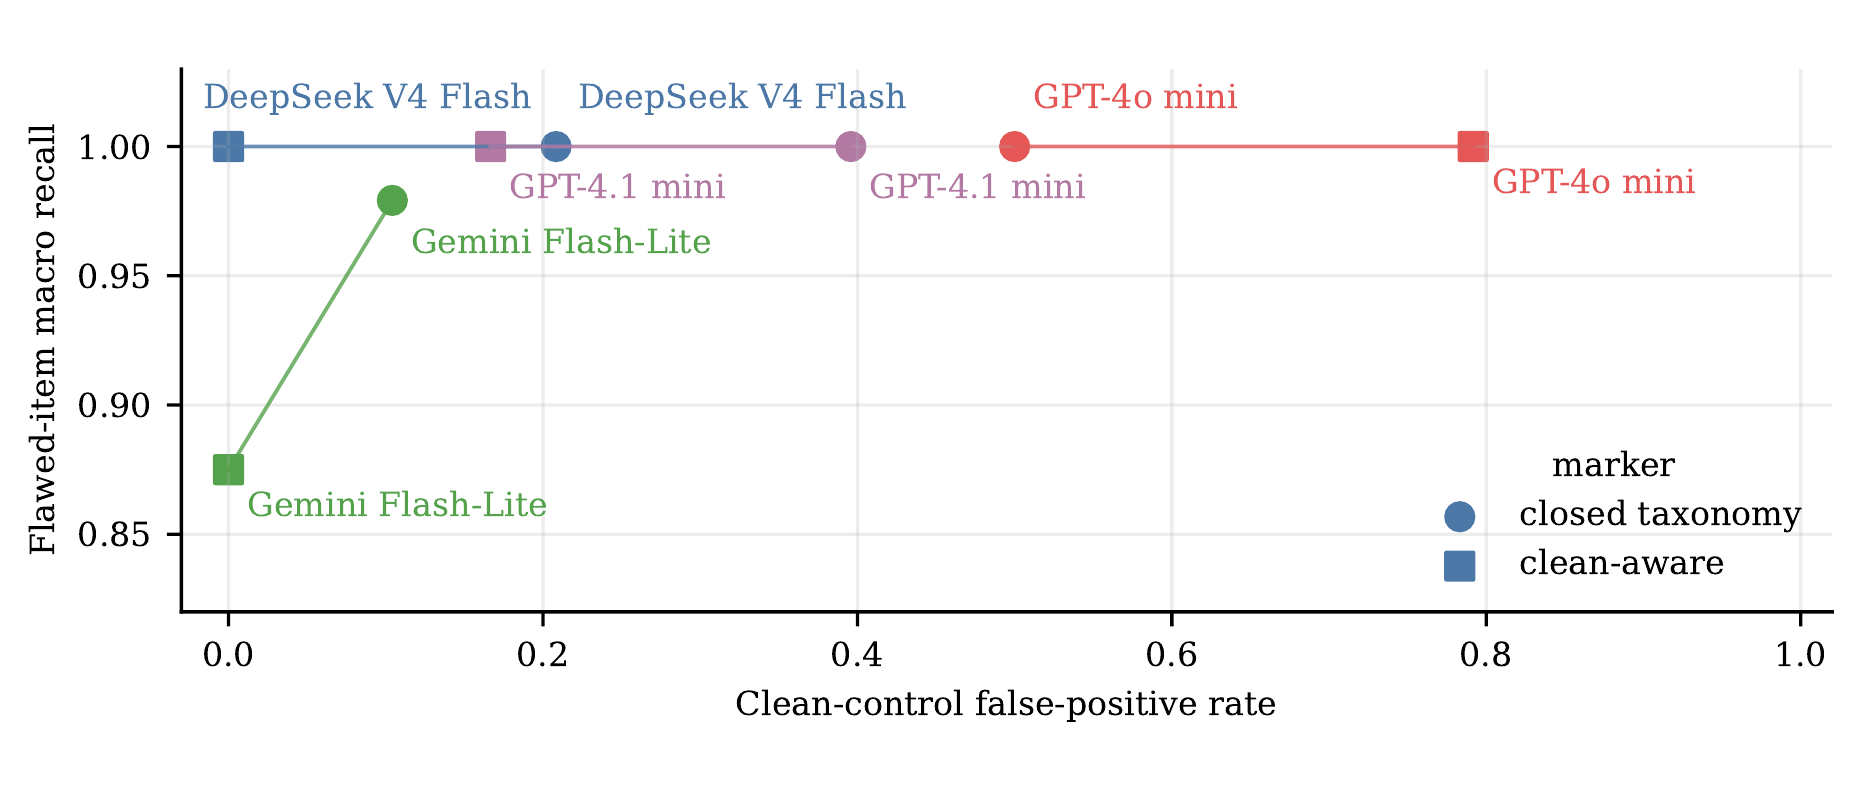
Flawed-item macro recall versus clean-control false-positive rate on the code surface, by model and prompt mode: every model is at or near ceiling recall, yet clean-control false-positive rates spread from 0 up to roughly 0.8.
Clean-control false-positive rate vs. flawed-item recall by model. Every model catches the planted flaws (recall near 1.0), but false-accusation rates on matched clean controls vary widely — the calibration gap that recall-only reporting hides. Open full-resolution figure (PDF) ↗

A detailed write-up of this work is coming soon. The full paper is available on arXiv.

← Back to home