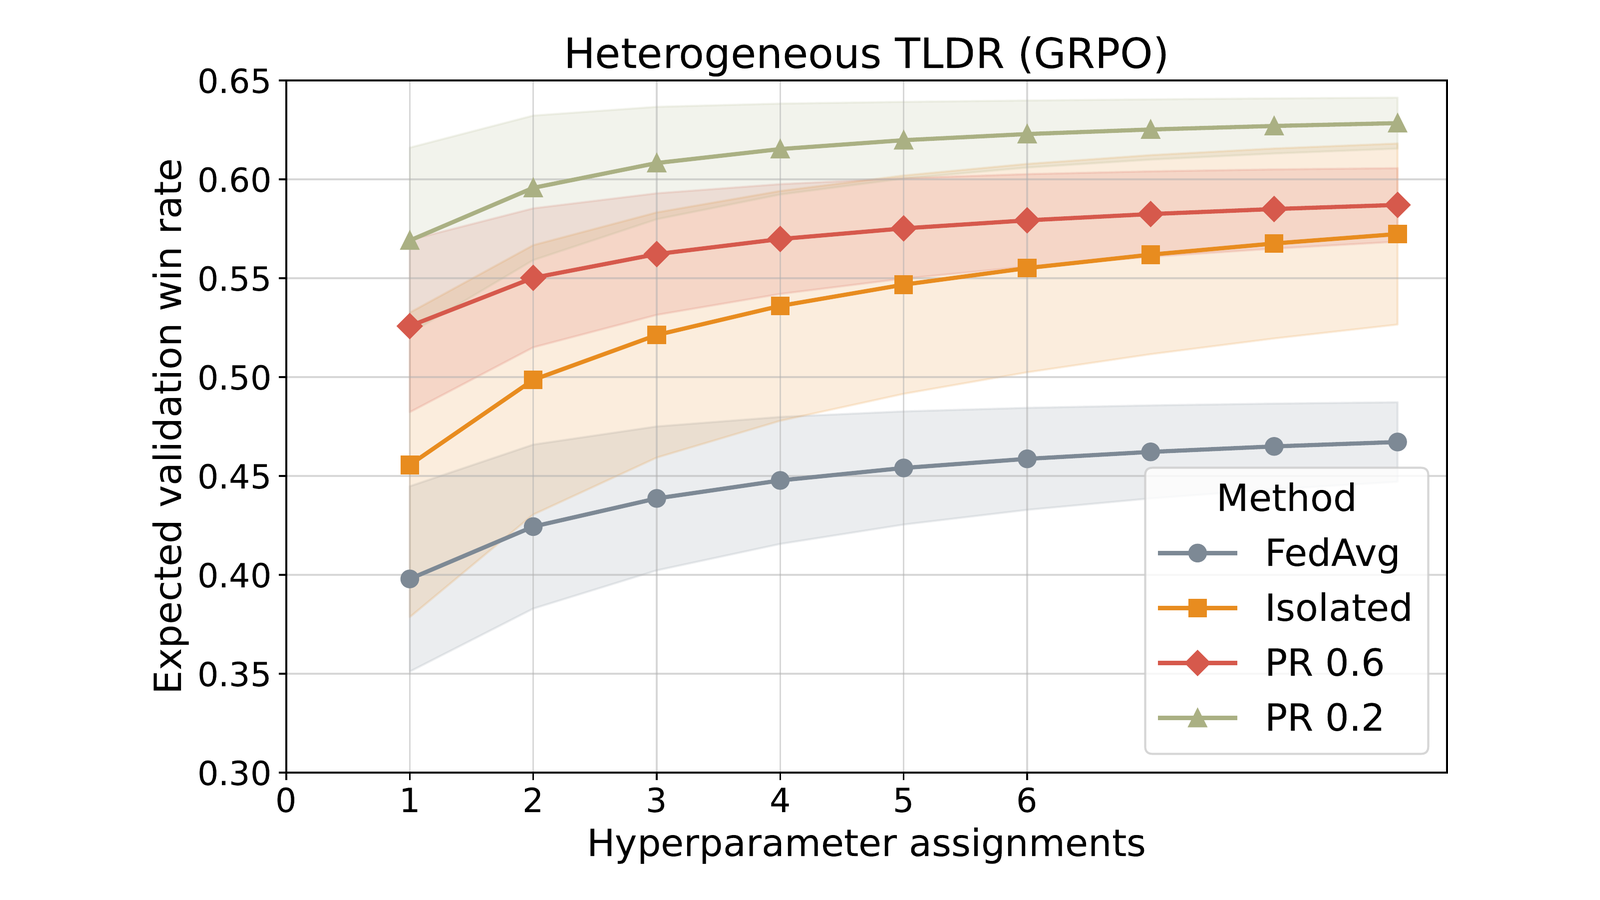
Publications / PRPO PRPO: Collaborative Online Policy Learning in Personalized RLHF A. Vladimirov, E. Gurov, V. Smirnov, V. Solodkin, A. Beznosikov Preprint OpenReview ↗Figure Personalized RLHF on heterogeneous TLDR (GRPO): PRPO (PR) sustains a higher expected validation win rate than isolated and FedAvg training as more clients collaborate. Open full-resolution figure (PDF) ↗ A detailed write-up of this work is coming soon. ← Back to home