Publications  /  Same Beliefs, Different Policies

Same Beliefs, Different Policies: Learning Reusable Representations for Early Stopping in LLM Reasoning
J. Ni, D. Abulkhanov, V. Smirnov, M. Leippold, E. Ash, T. Baldwin, A. Shelmanov, M. Sachan

Under review ICLR 2027

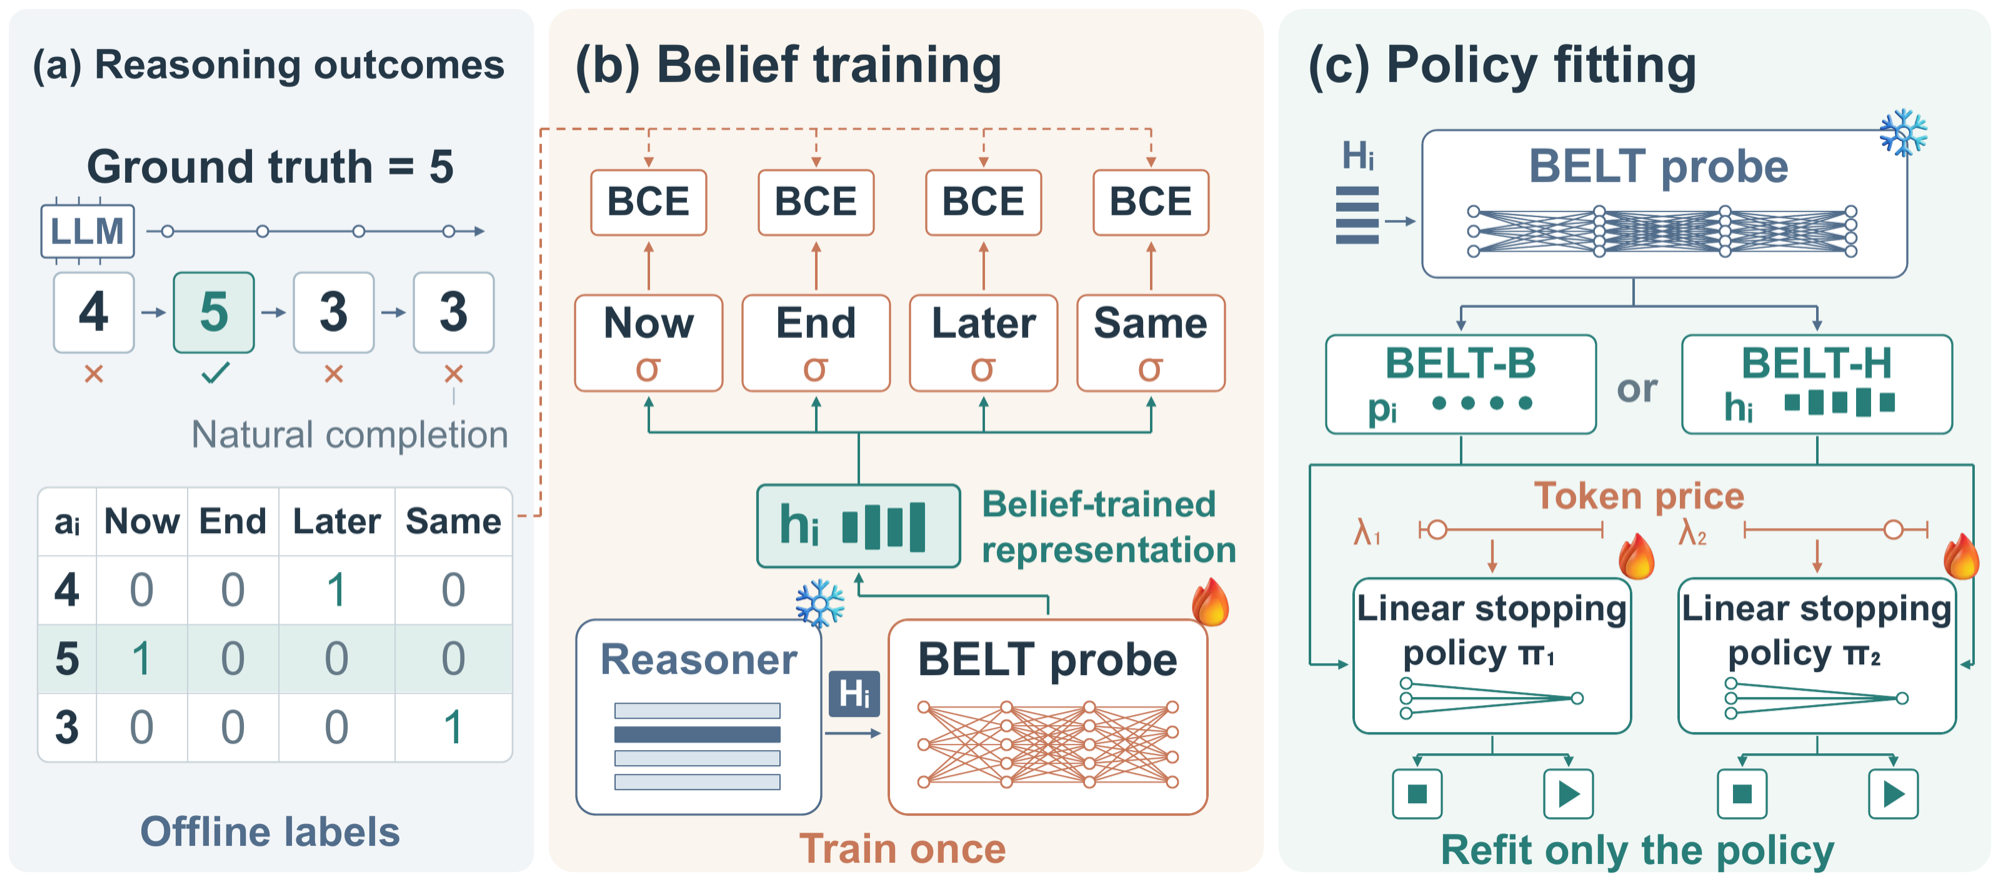
BELT overview: (a) offline reasoning traces are labelled with outcome beliefs; (b) a probe on the frozen reasoner's hidden states is trained once on four outcome-prediction objectives; (c) linear stopping policies are fitted on the frozen belief features for different token prices.
BELT overview. (a) Label offline traces to supervise outcome beliefs. (b) Jointly train the BELT probe with four objectives of outcome prediction. (c) Fit stopping policies on frozen features for token prices; alternatively, fit once and vary its threshold. Both reuse one representation. Open full-resolution figure (PDF) ↗

A detailed write-up of this work is coming soon. The full paper is available on arXiv.

← Back to home